AI Computing
High-performance compute infrastructure for model training, fine-tuning and large-scale inference — GPU workstations, AI servers and cluster-scale deployments.
Browse all 6 productsProducts
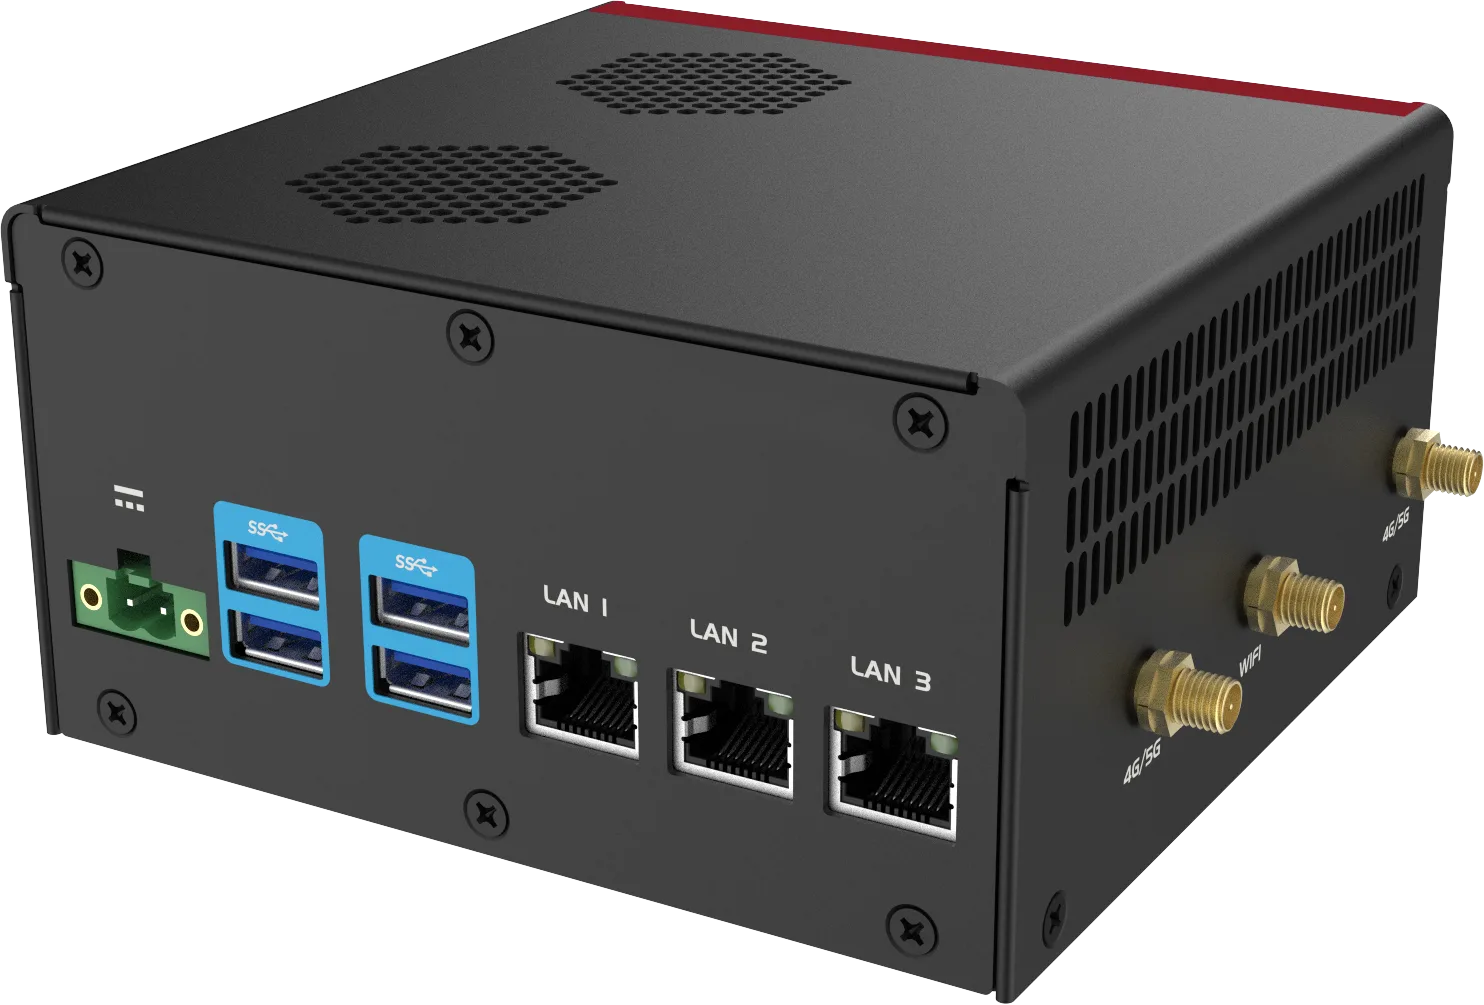
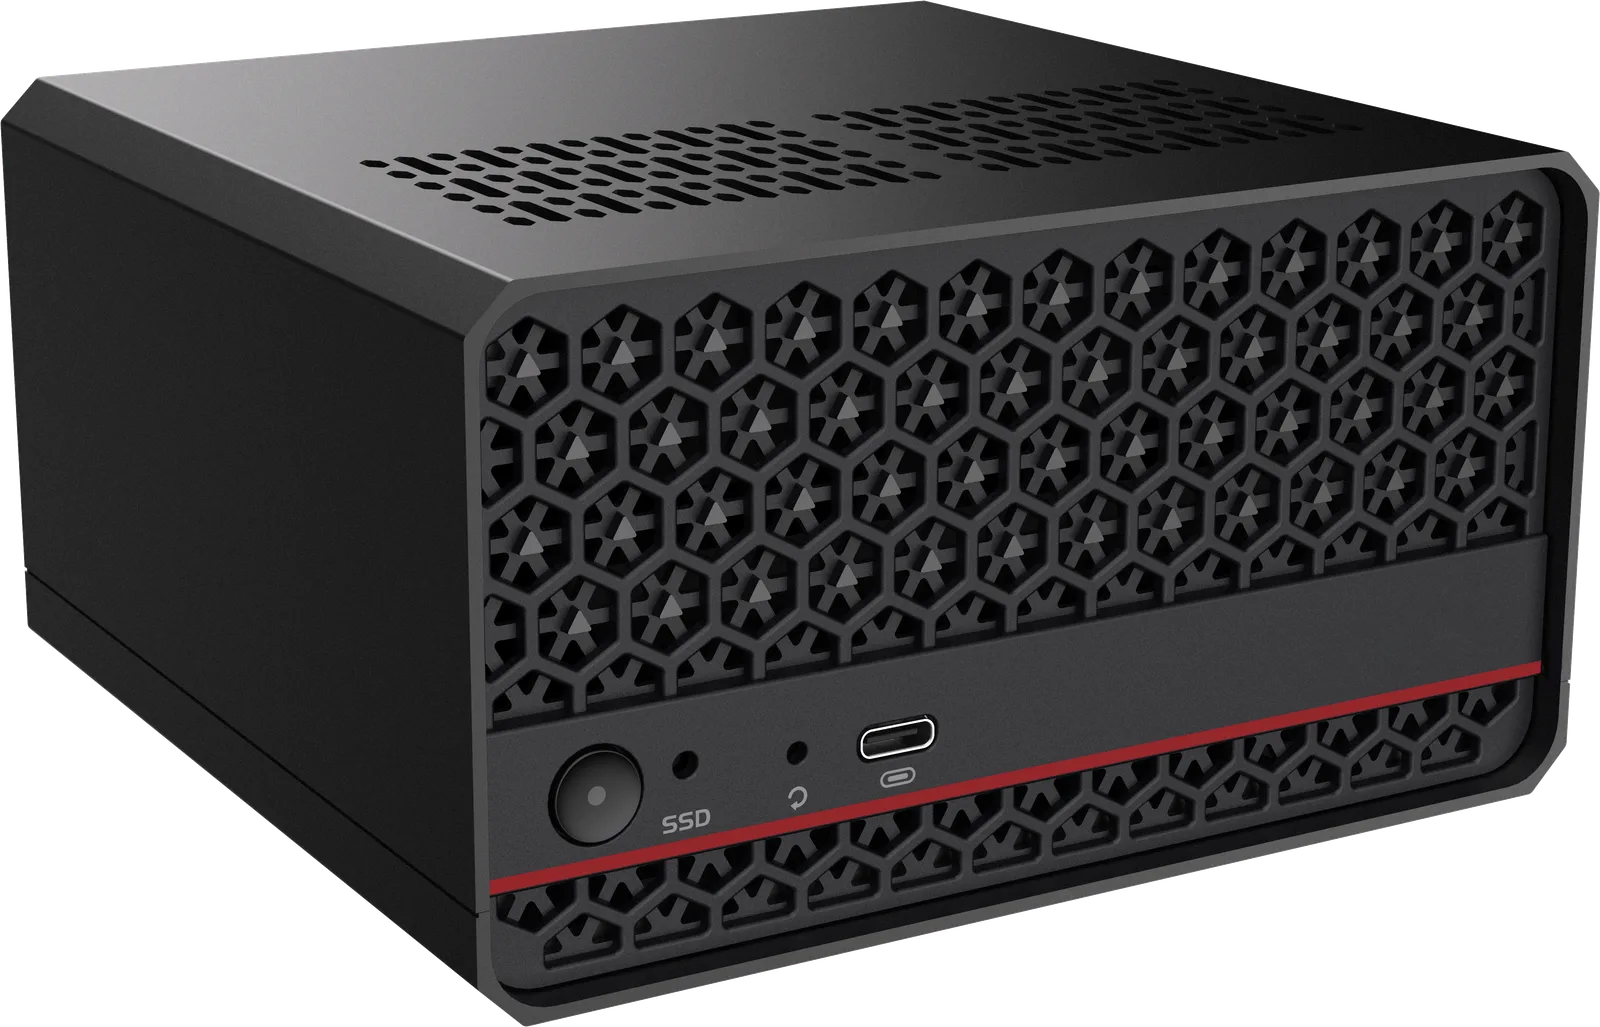
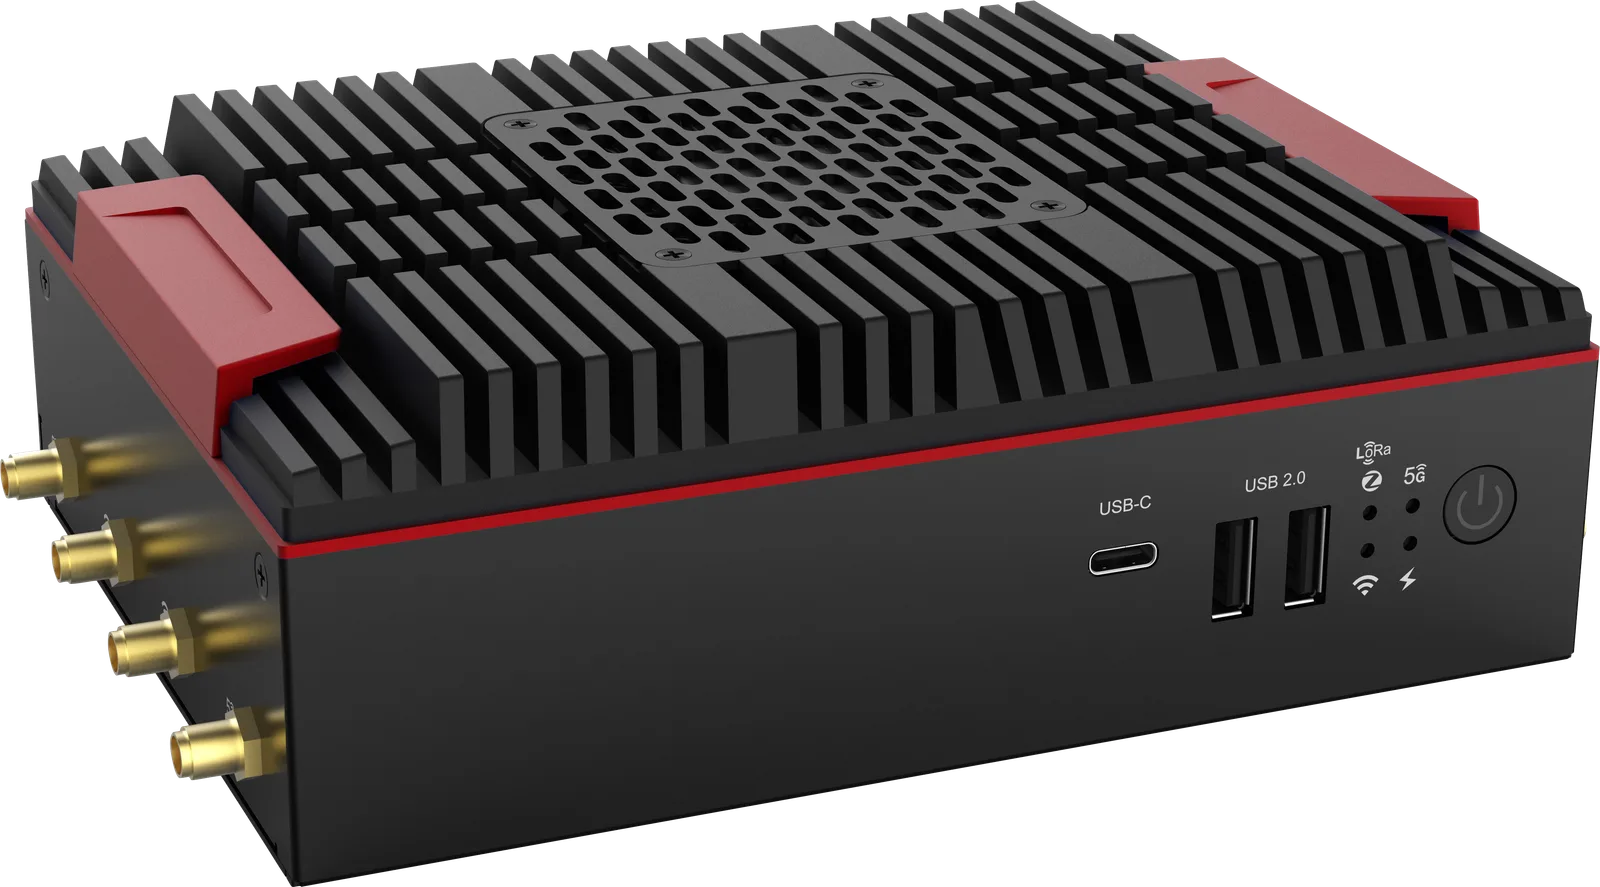
AI initiatives stall on compute bottlenecks: a training run that exhausts memory mid-epoch wastes days of preparation; an inference cluster that can't scale with demand loses customers at peak. Aicotek AI computing systems are engineered for sustained workload performance, from single-GPU development to multi-node training clusters.
One architecture spans development to production: current platforms scale from desktop workstations with 4-8 GPUs to liquid-cooled server nodes with NVLink/NVSwitch interconnect — isolated experimentation environments, or unified resource pools orchestrated across a cluster. That protects R&D investment for LLM fine-tuning, computer vision research, scientific simulation and generative AI services. Air-cooled configurations suit office-lab deployments where noise matters; direct liquid cooling enables maximum GPU density for data center efficiency.
For MLOps pipelines, containerized orchestration platforms provide automated experiment tracking, model versioning and elastic inference scaling, with high-speed InfiniBand or RoCE networking for distributed training synchronization. Shared parallel storage and model registries streamline collaboration across data science teams.
Accelerator and software stack options vary by workload. The range includes NVIDIA, AMD and Intel systems, with Kubernetes, Slurm and selected bare-metal configurations for installations where virtualization overhead is unacceptable for HPC-style performance.